 Athrael.net
Introduction to GPU Inference
How language models run on GPUs, explained with interactive diagrams.
1 lesson, 3 more coming
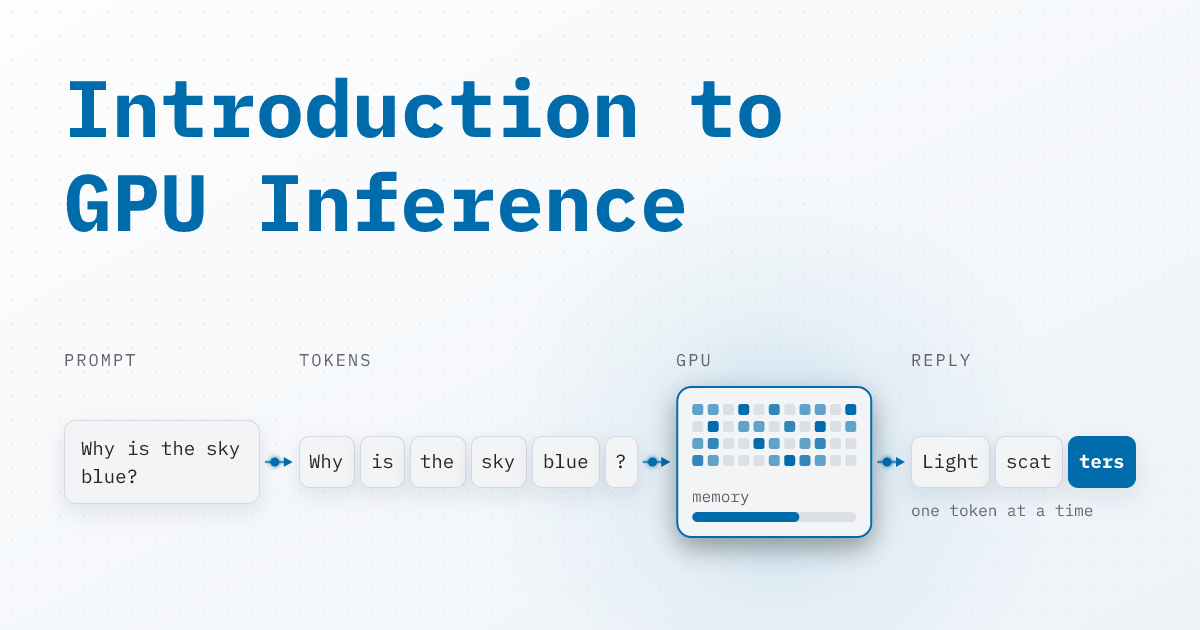
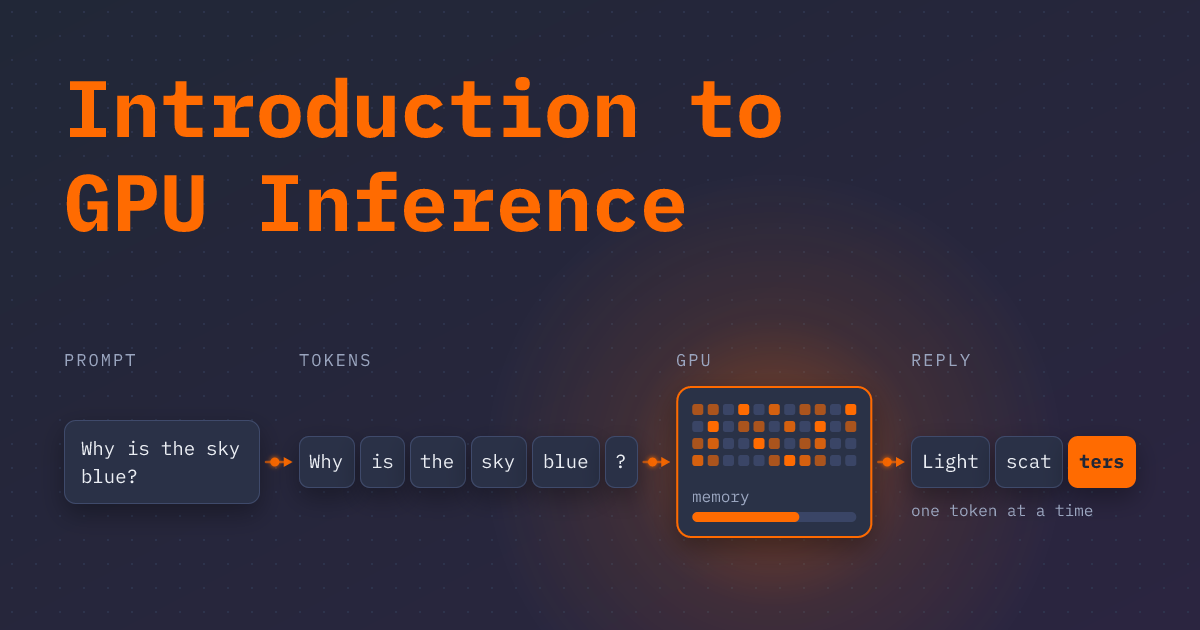
By the end you can explain what happens between sending a prompt and reading the reply, and say why language models run on GPUs and what limits them.
Foundations
- From prompt to reply10 min
What happens between sending a prompt and reading the reply.
- Serving many requests at onceComing soon
One GPU answers several people at the same moment. The lesson shows how it does that and why each of them waits a little longer as a result.
- How speed is measuredComing soon
What time to first token and tokens per second measure, and what makes them change.
- Picking a model and a GPUComing soon
How to tell whether a model will run on a given GPU once real conversations are using its memory.
Attributions: Fish Audio Drama 3 for the narration, in the author's own voice.